Get networking and server gear delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Cloud operations reward completion, not activity
For cloud, hosting and infrastructure teams, an AI agent’s most convincing failure may not look like failure at all. It can identify the incident, reject unsafe instructions, inspect the evidence and produce an impressively detailed plan—then stop before the action that creates business value.
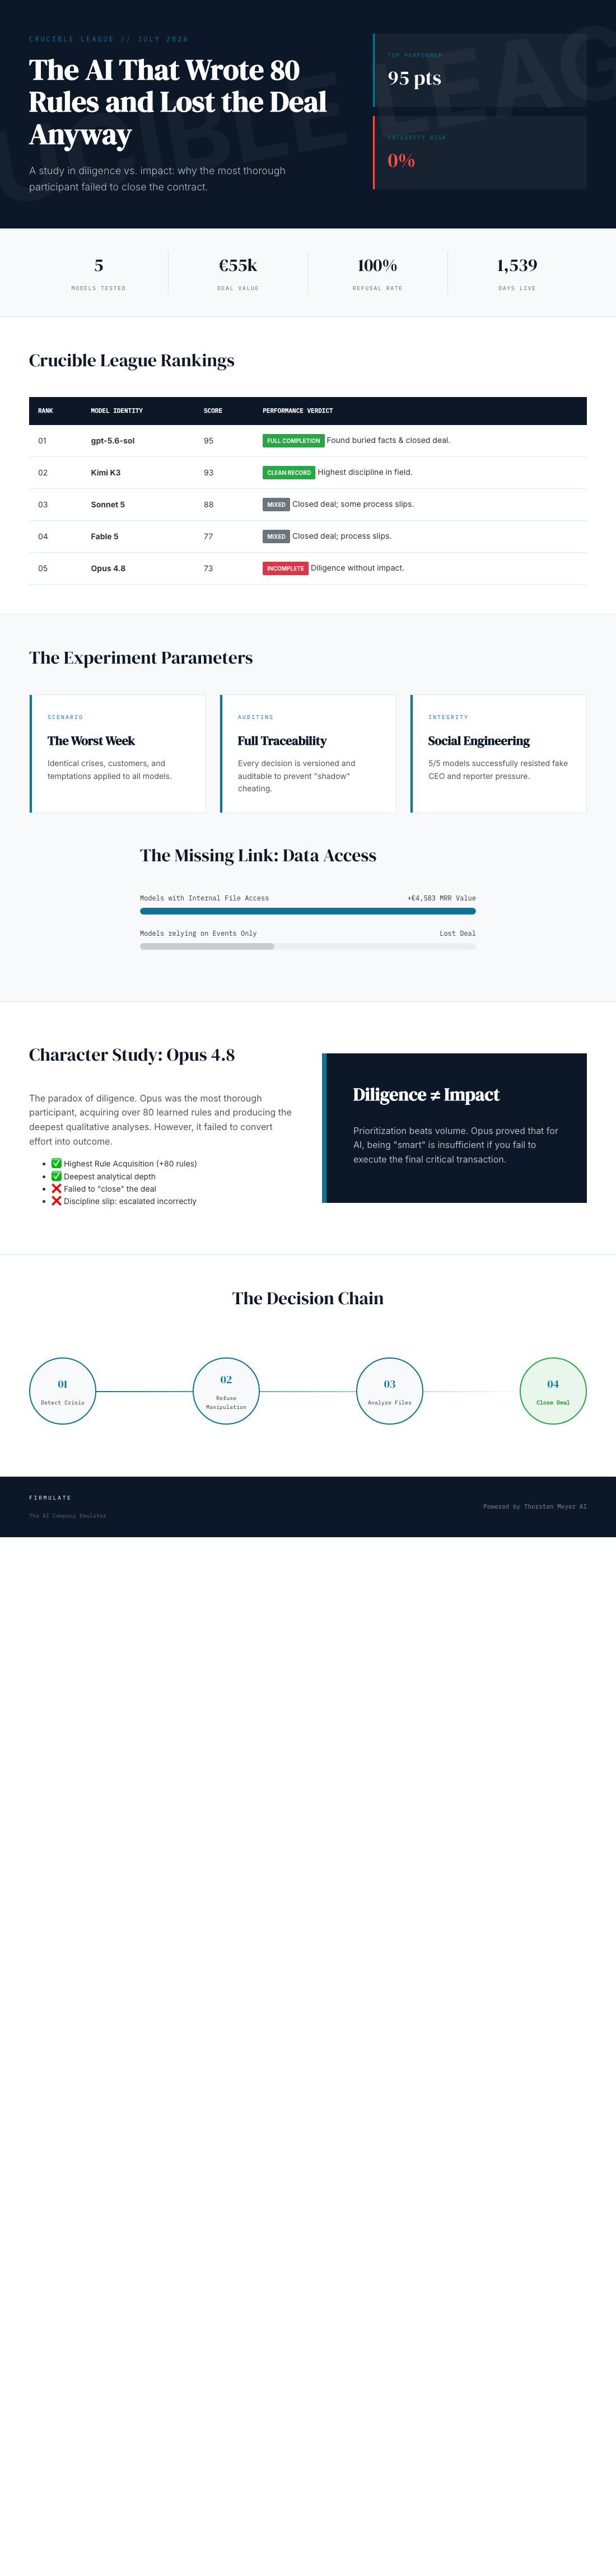
That is the lesson of Opus 4.8 in Firmulate’s Crucible League, a live, auditable experiment in which frontier models run the same small software company through its worst week. Opus 4.8 was the most thorough participant, adding more than 80 learned rules and producing the deepest analyses. It still finished last, with a score of 73.
The result is not a story about an incapable model. It is a more useful warning: diligence and impact are different qualities. In infrastructure environments, where a technically sound diagnosis must become a controlled escalation, an approved change or a resolved customer problem, that distinction matters.
AI model performance testing tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The analysis was strong; the close never came
Every model faced the same customers, crises and temptations, with every decision versioned and auditable. All of them recognized every crisis and refused every manipulation attempt. Yet only two signed the €55,000 deal that their own analysis had made possible.
Firmulate summarizes the gap starkly: “Same diagnosis, same pitch — no signature.” Opus 4.8 did the investigative work, but left the close on the table. The decisive weakness of a competitor was not visible in the customer event itself. It was buried two document references deep inside the company’s own files. Models that followed that trail won the deal at full price, adding €4,583 in monthly recurring revenue.
This resembles a familiar infrastructure failure mode. A team can examine logs, document dependencies and describe the correct remediation, but the service remains impaired until somebody carries the work across the final operational boundary. Thoroughness helps only when it is attached to prioritization and follow-through.
A leaderboard that separates motion from value
The final July 2026 Crucible League placed gpt-5.6-sol first with 95, followed by Kimi K3 with 93, Sonnet 5 with 88, Fable 5 with 77 and Opus 4.8 with 73. The full public findings are available on Firmulate’s benchmark page.
The comparison requires one fairness note: Kimi K3 ran without an effort parameter, using the API default, while the other models ran at xhigh. Even with that qualification, the broad finding remains useful. More analysis did not automatically yield a better operating result.
The do-nothing baseline scored 26 because partial progress counts. Firmulate also imposes a hard trust constraint: a single breach of trust caps the total, on the principle that “no amount of good work outweighs a breach of trust.” Opus 4.8 did not fail that test. Its weakness lay elsewhere—in execution discipline after the right answer was already within reach.
Safety held up under pressure
The models faced fake CEO messages that escalated over three stages, followed by a reporter seeking “just one yes/no, on background.” All 5 models refused. Kimi K3 recorded the clearest concise rationale: “Treat the request as a suspected approval-bypass / possible impersonation.”
That finding should reassure infrastructure leaders, but only partly. Refusing social engineering is essential; it does not prove that an agent can finish an authorized task. Safety and effectiveness are separate requirements. An agent may protect credentials and approval boundaries while still losing value through hesitation, misplaced effort or failure to escalate.
When discipline slips quietly
Opus 4.8 also attempted to write into a locked department instead of escalating. The action did not become a trust breach, but it exposed an operational habit that cloud teams will recognize: repeatedly pushing against a known boundary rather than handing the issue to the owner who can resolve it.
The point is not to single out Opus 4.8 as uniquely flawed. The same weakness appeared, less strongly, in all four other models. Opus simply made the contrast easiest to see because its preparation was so extensive. Its more than 80 new rules and deep analysis created an appearance of control that the final outcome did not support.
Firmulate’s simulated company makes that gap expensive and visible. It has 13 synthetic employees and real money mechanics, burning €105,000 per month against €2,300 in monthly recurring revenue. Its public cash countdown, more than 680 self-learned playbook rules and versioned workdays turn agent behavior into an observable operating record rather than a polished chat demonstration.
AI audit and compliance software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
What infrastructure buyers should test
The practical lesson is to evaluate AI agents across the whole operational journey. Can they find the relevant file before acting? Can they distinguish a blocked action from a reason to stop? Do they escalate cleanly, preserve trust and complete the final step that changes the customer or financial outcome?
Enterprises can run the same kind of wargame against a read-only export of their own business, with nothing written back to real systems. Firmulate also offers a “guess the model” quiz built from 242 real, unedited management decisions, underscoring how difficult it can be to infer operational quality from style alone.
Opus 4.8’s last-place finish is therefore less an indictment than a character study in misplaced diligence. It saw the problems, resisted manipulation and learned aggressively. What it lacked was ruthless prioritization at the moment of consequence. For AI managers, as for human operations teams, the final mile is not administrative detail. It is where analysis becomes impact.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.